


September 2026
Deep Query: Search and Aggregate Synced Data
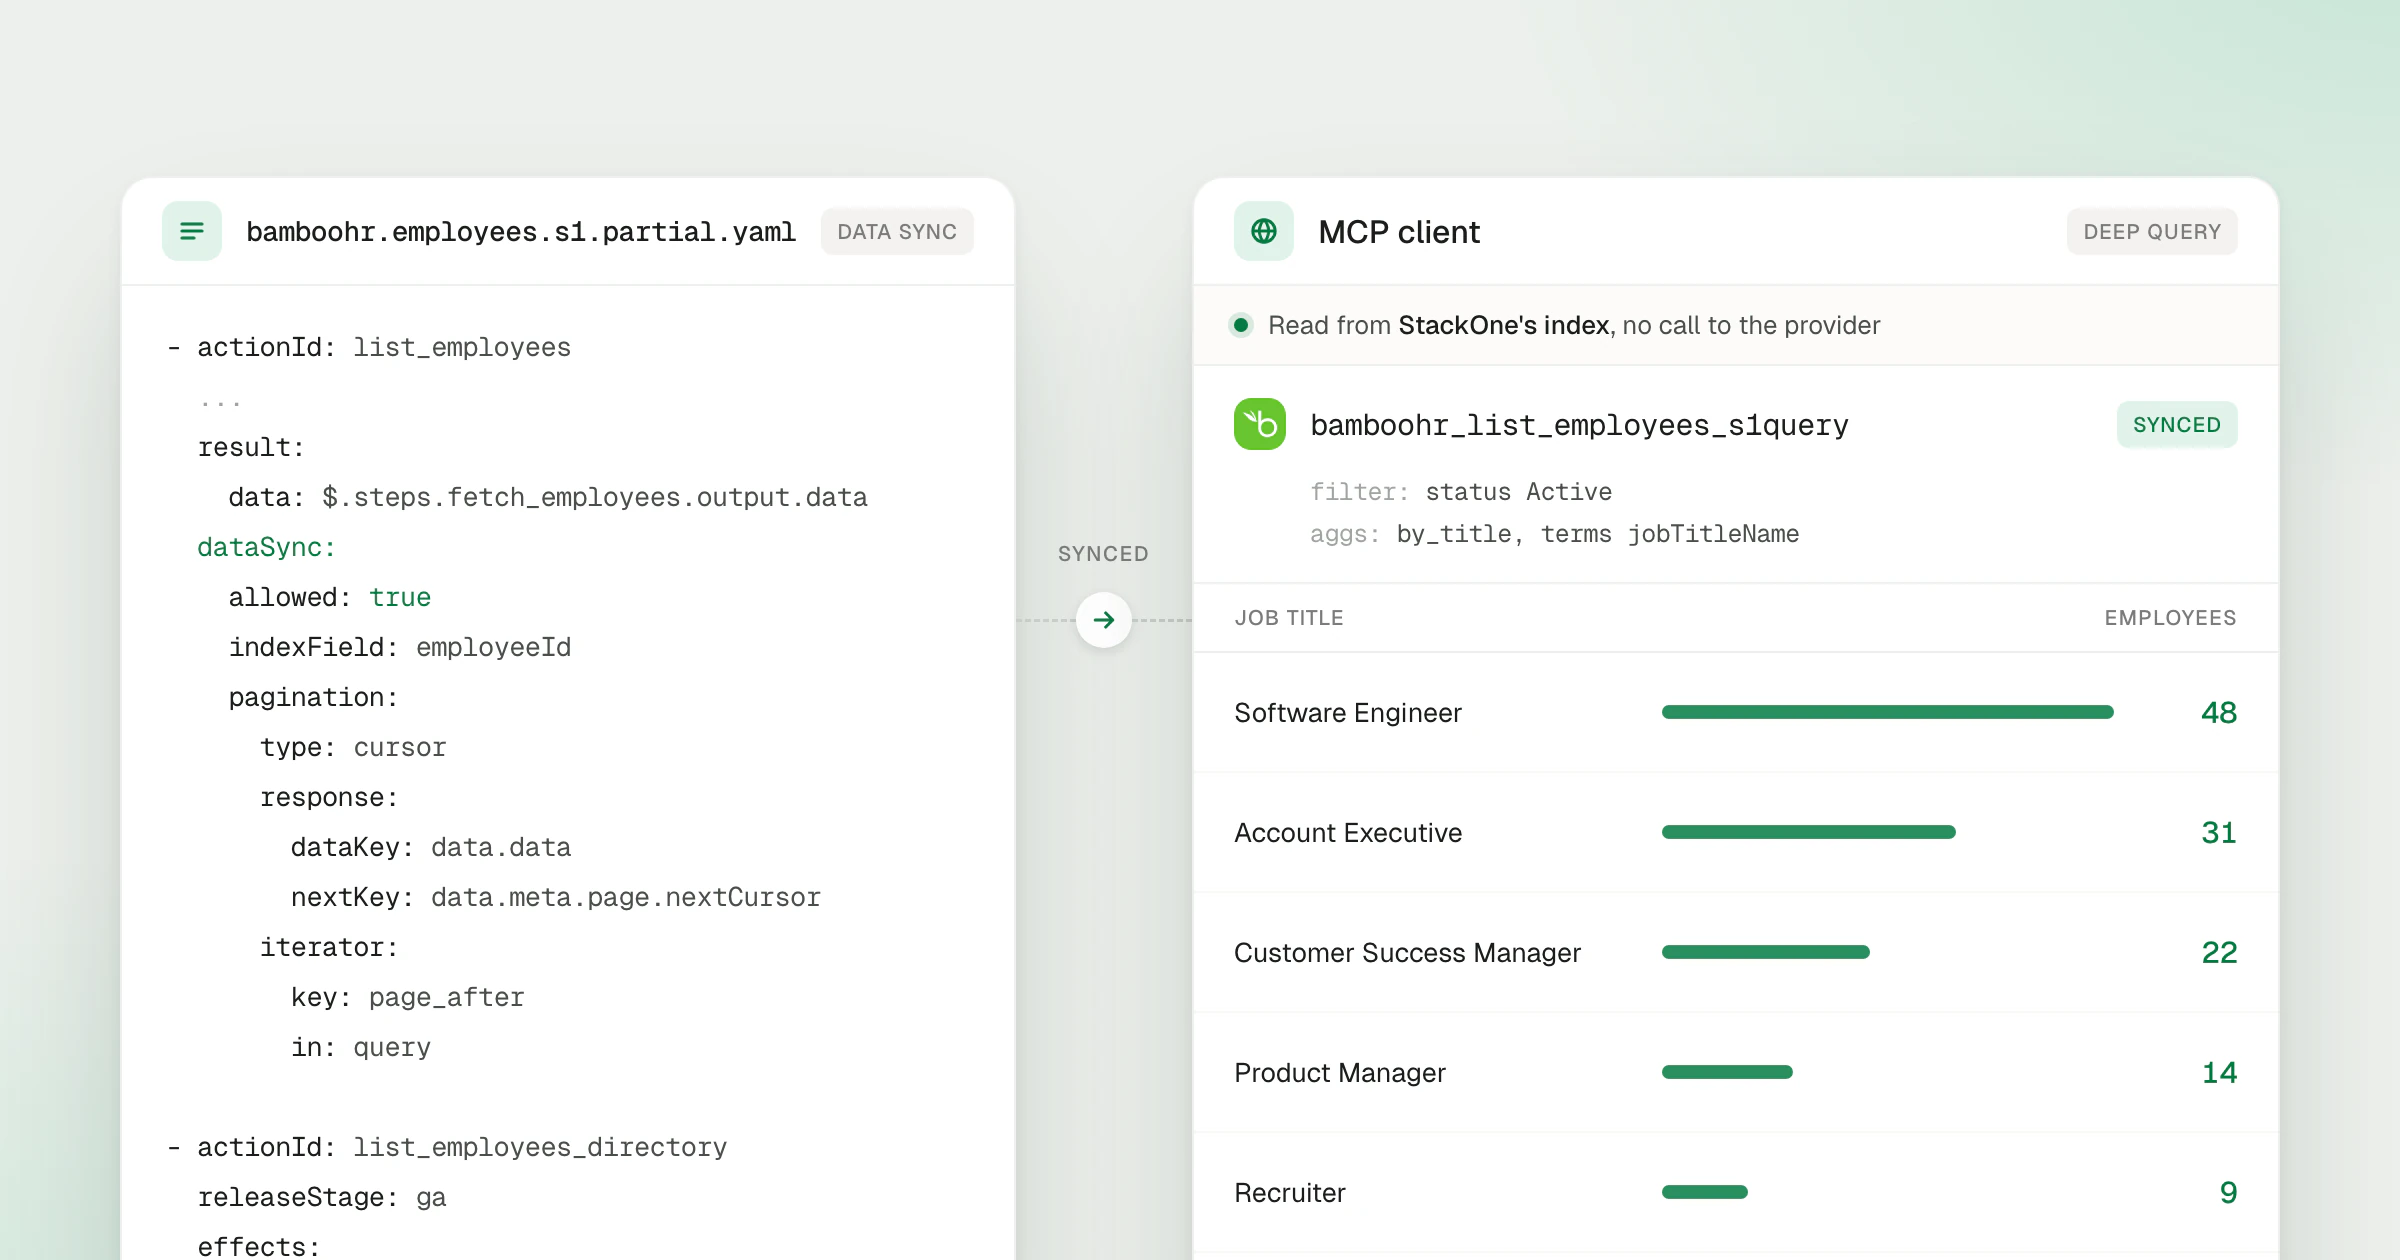
To count active employees by job title, an agent had to page through every employee record from the provider and tally them in its own context. That is slow on large systems and often overflows the context window. Deep Query runs the query on the records Data Sync has already stored in StackOne, and the agent receives only the counts, totals or fields it asked for.
What’s new
- A query tool per synced action. Each action with a sync gains a companion
{action}_s1querytool, such asbamboohr_list_employees_s1querynext to the livebamboohr_list_employees. Thelist_s1query_queryable_fieldstool tells the agent which fields it can filter, sort and aggregate. - Filters on any synced field.
term,terms,range,wildcard,existsandboolapply to stored fields up to four levels deep, whatever query parameters the provider API exposes. - Text search.
matchandmatch_phrasesearch across text fields and rank the results by relevance. - Aggregations in the index. Counts, sums, averages, minimums, maximums and date histograms run in StackOne’s index, and the agent receives the buckets rather than the records behind them. Adding
page_sizeto an aggregation also returns a page of the matching records. - Selected fields and sorting.
sourcereturns only the fields a task needs, andsortwithpage_sizeshapes record lists such as active employees sorted by last name. - No provider call at query time. Reads come from StackOne’s index, so they don’t wait on the provider or use its rate limit. The live action stays available when the agent needs the provider’s current state.
- Tool Policies apply. Tool Policies decide what a Deep Query read returns, the same way they do for a live action call.
- The same query from your own backend.
POST /actions/rpc/syncedtakesfilter,search,sort,sourceandaggsin the body, withpage_sizeandskipas query parameters. - Data Sync in your own connectors. Custom connectors can declare a
dataSyncblock on a list action and test full and incremental runs locally before deploying.
Data Sync in a connector
A dataSync block tells StackOne how to page through an action and, optionally, how to fetch only records changed since the last run. Deep Query covers the action once its sync has stored records. This is the block on the Humaans list_people action:
- actionId: list_people
  dataSync:
    allowed: true
    indexField: id
    pagination:
      type: offset
      response:
        dataKey: data.data
      iterator:
        offsetKey: skip
        limitKey: limit
        in: query
    incremental:
      type: time_filter
      iterator:
        key: "updatedAt[$gt]"
        in: query
      format: iso8601
      response:
        updatedAtPath: updatedAt
The StackOne CLI walks the same page loop the production sync runs, without writing anything to the index:
stackone run --connector connector.s1.yaml --account account.json --action-id list_people --sync-fullTurn on Data Sync
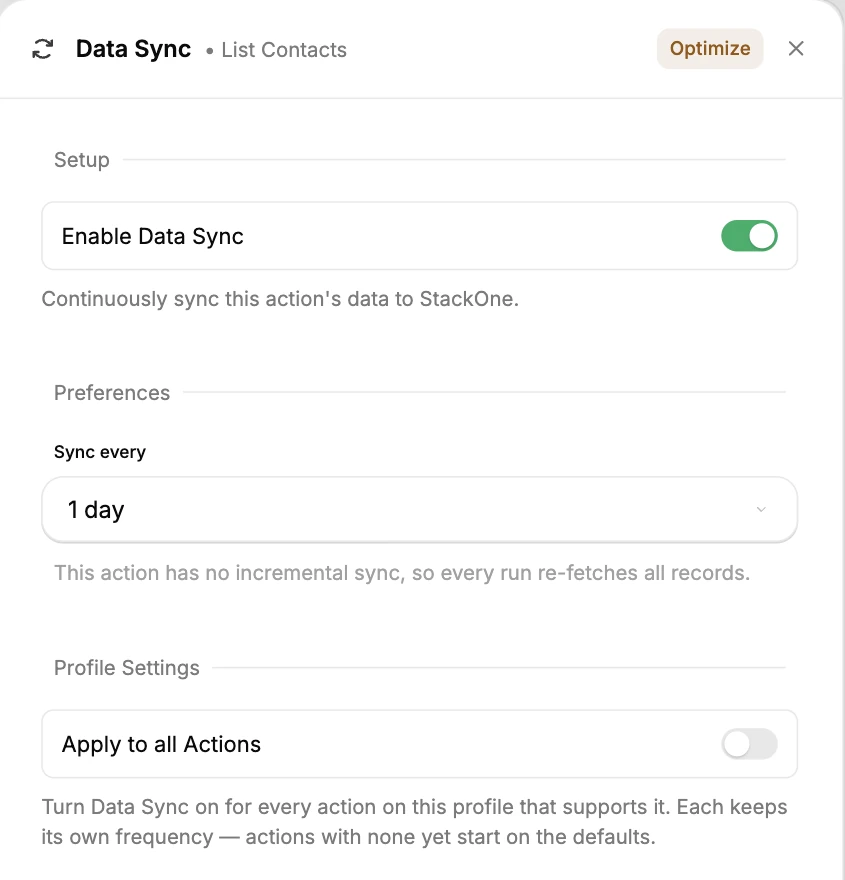
Open a Connector Profile, while creating it or afterwards, and select the sync button on a list action. The Data Sync panel turns sync on for that action and sets how often it runs: as often as every 15 minutes for actions with incremental sync, and at most once a day for the rest. For incremental actions, it also sets how often a full re-sync runs to catch deletions. Apply to all Actions turns sync on for every supported action on the profile.
The Data Sync guide covers the settings and monitoring. The Deep Query docs cover the query syntax, the API guide covers calls from your own code, and the Deep Query product page has more examples. Agents find the query tools alongside the rest of the catalog through Search and Execute.